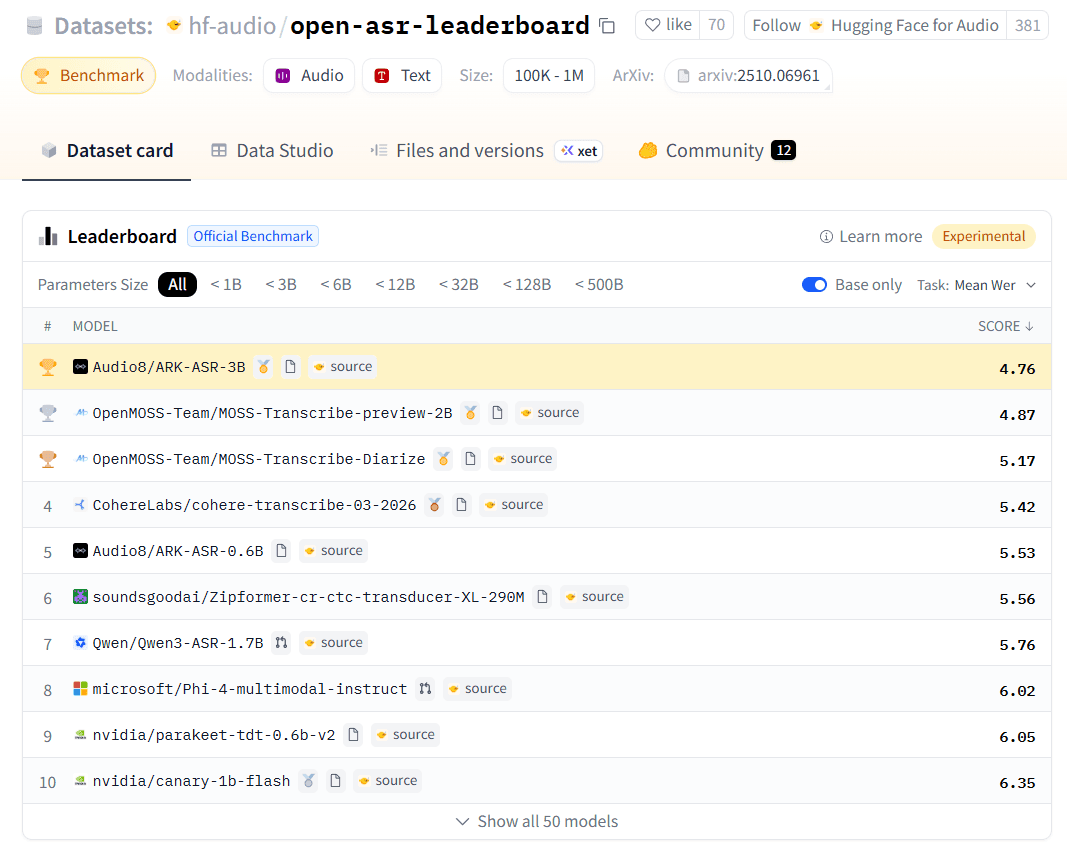
Speech recognition in the cloud, on workstations, and on mobile devices presents different engineering challenges. Audio8 ASR is built as a family of models, each optimized for its intended deployment environment, rather than as a single model simply consolidated as an all-in-one.
Cloud services optimize for accuracy and throughput, desktops for responsiveness, and phones must balance memory, power and privacy at once. Larger models in the family take the most demanding recordings; compact models bring recognition to ordinary CPUs and mobile devices. Each size is tuned for a different balance of quality, cost and device capability.
| Model | Scale | Primary runtime | Languages |
|---|
| Audio8 ASR 3B | 3B | High-performance GPU | 19 languages (Chinese, English, German, Japanese, French, Korean, Spanish, Polish, Italian, Romanian, Hungarian, Czech, Dutch, Finnish, Croatian, Slovak, Slovenian, Estonian, Lithuanian) |
| Audio8 ASR 0.6B | 0.6B | GPU / workstation / server | 19 languages (Chinese, English, German, Japanese, French, Korean, Spanish, Polish, Italian, Romanian, Hungarian, Czech, Dutch, Finnish, Croatian, Slovak, Slovenian, Estonian, Lithuanian) |
| Audio8 ASR 0.1B | 0.1B | CPU / edge / mobile | 7 languages (Chinese, English, Cantonese, French, Japanese, German, Korean) |
Three models, three considerations
Audio8 ASR 3B prioritizes recognition quality for difficult and multilingual audio. Audio8 ASR 0.6B balances quality with throughput and serving cost. Audio8 ASR 0.1B targets private, local inference on mobile and edge hardware. All three turn continuous sound into useful text; runtime and hardware adaptations are how each reaches a product, and do not change the family structure.
From sound to text
A recording first becomes a stable acoustic representation. The model then follows speech, pauses and context along the timeline before producing readable text, preserving pronunciation while suppressing background noise, repeated fragments and silence.
Large models show their value where audio is hardest to hear: far-field attenuation, several people talking, uncertain vocabulary from specialist terms, and links between the start and end of a long recording. Smaller models are about predictable, controllable runtime cost.
So the differences inside Audio8 ASR should not be judged by parameter count alone. On a GPU the same task can trade for more context and throughput; on a CPU or a phone, every computation has to be cheaper.
Audio8 ASR 3B: highest accuracy for the hardest audio
Audio8 ASR 3B is the family's heavy hitter for accuracy, for work where errors are costly: meeting records, interview transcription, media subtitles and detail-preserving multilingual transcription.
Audio8 ASR 0.6B: the practical balance
Audio8 ASR 0.6B holds the all-rounded middle ground. It keeps recognition reliable on real recordings while giving GPU services and local workstations a more manageable resource budget. For teams that need batch processing without spending the whole budget on a single inference, it is the natural starting point.
The 0.6B line also ships in quantized, CPU-oriented and general-runtime builds. They free the model from a strict CUDA dependency, so ordinary servers and edge hosts can take part in transcription with less storage and memory pressure.
Audio8 ASR 0.1B: Small means rethinking the architecture
When a model has to stay resident on a device, parameter count, peak memory and power decide whether the product can exist at all. Audio8 ASR 0.1B targets local voice input, field notes, offline captions and privacy-sensitive applications. Its ONNX Runtime path runs on x86 and ARM CPUs, with INT8 and INT4 variants that make deployment practical without a full deep-learning environment.
For phones or edge devices on the go, stable response time, controlled memory and low power matter more than peak performance.
Keep speech recognition on the device
Mobile is not a smaller server. Apps move between foreground and background, available compute changes with battery and temperature, and users have good reasons to keep private audio local. For the 0.1B line, on-device means designing for these constraints and providing a concrete path for each hardware target.
A low-power path for Apple hardware
Audio8 ASR 0.1B iOS-ANE combines Core ML and ONNX Runtime to run on the Apple Neural Engine in iPhone and iPad, with a Swift integration layer. Taking recognition off the CPU and GPU allows sustained transcription on a steadier power curve, with recordings staying on the device.
A standard runtime for general devices
The same line also ships as Audio8 ASR 0.1B ONNX Runtime. It removes the CUDA, PyTorch and Transformers dependencies, runs on ordinary x86 and ARM CPUs, and offers INT8 and INT4 variants to cut storage and memory further.
Recognition performance across the family
On public speech-recognition evaluations spanning Chinese CER, English WER and multilingual transcription, Audio8 ASR sits in the leading group. From the 3B model in the cloud to the 0.1B model on a device, each is designed to give dependable results on its target hardware, including recordings with noise, distance, accents and several speakers.
| Evaluation area | Leading behavior |
|---|
| Recognition quality | Leading-group Chinese CER, English WER and multilingual results |
| Difficult audio | Stable under noise, distance, accents, overlap and long recordings |
| Runtime efficiency | Strong real-time factor, first-token latency and throughput |
| Device cost | Lower VRAM and memory use with controlled power draw |
From high-accuracy recognition at 3B to on-device operation at 0.1B, Audio8 ASR brings speech understanding to every model size, bringing recognition quality and deployment cost together.
Choosing the right model
Start with Audio8 ASR 3B when accuracy on difficult audio is prioritized. Choose Audio8 ASR 0.6B for general GPU serving and a more balanced cost profile. When the deployment is mainly a CPU, an edge device or a phone, consider Audio8 ASR 0.1B and the runtime built for that hardware.
The optimal method to choose starts with the audio source, how fast a result must come back, how much memory is available, and which recordings cannot leave the device. A model family exists to turn these constraints into a clear choice.
Limitations and responsible use
Automatic transcripts may be affected by noise, accents, overlapping speech, specialist terms and source quality, and should not be treated as verified records without review. Medical, legal, financial and other high-risk uses require human oversight. Obtain consent before processing personal voices or sensitive conversations, and protect stored audio and text with suitable access and retention rules.
Audio8-ASR / Model Family
From high-accuracy 3B transcription to low-power recognition on phones, Audio8 ASR is designed to deliver the right level of performance for each device.